Seedream 4.5 is a next-gen text-to-image model optimized for typography—crisper text rendering, stronger prompt adherence, and up to 4K output for posters and brand visuals. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
Idle
$0.04per run·~25 / $1
Related Models
README
Seedream 4.5
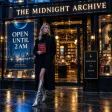
Seedream 4.5 is ByteDance’s high-resolution image generation model, upgraded through large-scale training and architecture refinement. It is especially strong at typography, poster composition, and branded visuals, with clear text rendering and strong prompt adherence.
Model highlights
- Enhanced typography – Renders sharp, legible text for posters, logos, UI, and marketing layouts.
- Designer-level composition – Handles complex poster-style layouts with clear hierarchy (title, subtitle, body text, logos).
- Strong prompt adherence – Closely follows detailed descriptions for subjects, layout, and style.
- High-resolution output – Supports custom width/height subject to the limits in the current input schema.
Recommended use cases
- Poster, banner, and KV design with embedded text
- Brand visual, logo, and campaign asset creation
- E-commerce product imagery and hero shots
- Social media graphics where typography is part of the design
- Presentation, landing-page, and in-app visuals
Pricing
- $0.04 per generated image
How to use
-
Enter your prompt Describe the subject, composition, text elements (e.g., title / subtitle / tagline), and overall style.
-
Set
size(width & height) Choose pixel dimensions for your image. The model supports custom sizes as long as the dimensions satisfy the current input schema and the model's limits. -
Run the job Click Run to generate the image, then refine your prompt or size for the next iteration.
Suggested resolutions
Example resolutions:
| Aspect Ratio | Suggested Resolution (W × H) |
|---|---|
| 1:1 | 2048 × 2048 |
| 4:3 | 2688 × 2016 |
| 3:2 | 2688 × 1792 |
| 16:9 | 2560 × 1440 |
| Square 4K | 4096 × 4096 |
Check the current input schema before using a custom size.
Notes
- For text-heavy posters, slightly higher resolutions (e.g. 2048×2048 or above) give noticeably cleaner typography.
- Keep logos and key text explicitly described (e.g. “white all-caps title at the top, small gray subtitle below”).
Model Comparison on WaveSpeedAI
Use Seedream 4.5 together with other models, depending on your priorities:
-
google/nano-banana-pro/text-to-image – Google’s Nano Banana Pro (Gemini 3.0 Pro Image family) offers another option for image generation; compare current prices and output quality for your task.
-
Tongyi-MAI/Z-Image-Turbo (available as Z-Image on WaveSpeedAI) – Tongyi-MAI’s 6B, 8-step turbo model focuses on maximum speed and throughput while keeping photorealism and bilingual (EN/ZH) support.
-
wavespeed-ai/flux-2-pro/text-to-image – FLUX.2 [pro] is a flagship, general-purpose model for cinematic quality and complex scenes, great when you need broad stylistic range beyond typography-heavy posters.
-
/seedream-v4 – The previous Seedream generation, strong at high-resolution illustration and diverse styles; Seedream 4.5 builds on it with noticeably better text rendering and layout control for branding work.
Rule of thumb:
- Choose Seedream 4.5 for posters, brand layouts, and any text-heavy creative.
- Choose Nano Banana Pro or Z-Image-Turbo after comparing speed, price, and quality on your inputs.
- Choose FLUX.2 [pro] for cinematic, style-flexible hero shots.
- Choose Seedream V4 when you want its familiar look or need variety across illustration styles.
Seedream v4.5 API — Quick start
Grab a WaveSpeedAI API key, then call POST https://api.wavespeed.ai/api/v3/bytedance/seedream-v4.5 with your input as JSON. The endpoint returns a prediction id. Start polling the result endpoint around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. On completed, read output values from data.outputs. Examples for Seedream v4.5 below.
HTTP example
set -euo pipefail

: "${WAVESPEED_API_KEY:?Set WAVESPEED_API_KEY}"

REQUEST_BODY=$(cat <<'JSON'
{
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "size": "2048*2048"
}
JSON
)

# 1. Submit the prediction.
SUBMIT_RESPONSE=$(curl --silent --show-error --fail-with-body \
  -X POST "https://api.wavespeed.ai/api/v3/bytedance/seedream-v4.5" \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer $WAVESPEED_API_KEY" \
  -d "$REQUEST_BODY")

TASK=$(printf '%s' "$SUBMIT_RESPONSE" | jq 'if has("data") then .data else . end')
PREDICTION_ID=$(printf '%s' "$TASK" | jq -r '.id')
if [ -z "$PREDICTION_ID" ] || [ "$PREDICTION_ID" = "null" ]; then
  printf 'Submission response did not contain a prediction id
' >&2
  exit 1
fi
RESULT_URL="https://api.wavespeed.ai/api/v3/predictions/$PREDICTION_ID/result"

# 2. Poll until the prediction finishes.
while true; do
  RESPONSE=$(curl --silent --show-error --fail-with-body "$RESULT_URL" \
    -H "Authorization: Bearer $WAVESPEED_API_KEY")
  RESULT=$(printf '%s' "$RESPONSE" | jq 'if has("data") then .data else . end')
  STATUS=$(printf '%s' "$RESULT" | jq -r '.status')
  case "$STATUS" in
    completed) printf '%s\n' "$RESULT" | jq '.outputs'; break ;;
    failed|cancelled|timeout|deleted) printf '%s\n' "$RESULT" | jq . >&2; exit 1 ;;
    *) sleep 2 ;;
  esac
done
Node.js example
const submitUrl = "https://api.wavespeed.ai/api/v3/bytedance/seedream-v4.5";
const apiKey = process.env.WAVESPEED_API_KEY;
if (!apiKey) throw new Error('Set WAVESPEED_API_KEY');

async function requestJson(url, options = {}) {
  const response = await fetch(url, options);
  if (!response.ok) throw new Error(await response.text());
  return response.json();
}

// 1. Submit the prediction.
const body = await requestJson(submitUrl, {
  method: "POST",
  headers: {
    "Authorization": `Bearer ${apiKey}`,
    "Content-Type": "application/json",
  },
  body: JSON.stringify({
        "prompt": "A cinematic shot of a city at sunset, soft golden light",
        "size": "2048*2048"
}),
});
const task = body.data ?? body;
if (!task.id) throw new Error("Submission response did not contain a prediction id");
const resultUrl = `https://api.wavespeed.ai/api/v3/predictions/${task.id}/result`;

// 2. Poll until the prediction finishes.
while (true) {
  const resultBody = await requestJson(resultUrl, {
    headers: { "Authorization": `Bearer ${apiKey}` },
  });
  const result = resultBody.data ?? resultBody;
  if (result.status === "completed") {
    console.log(result.outputs);
    break;
  }
  if (["failed", "cancelled", "timeout", "deleted"].includes(result.status)) throw new Error(JSON.stringify(result));
  await new Promise(resolve => setTimeout(resolve, 2000));
}
Python example
import json
import os
import time
from urllib.request import Request, urlopen

api_key = os.environ["WAVESPEED_API_KEY"]
headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}
payload = {
    "prompt": "A cinematic shot of a city at sunset, soft golden light",
    "size": "2048*2048"
}

def request_json(url, data=None):
    request = Request(url, data=data, headers=headers, method="POST" if data else "GET")
    with urlopen(request) as response:
        return json.load(response)

# 1. Submit the prediction.
body = request_json("https://api.wavespeed.ai/api/v3/bytedance/seedream-v4.5", json.dumps(payload).encode())
task = body.get("data", body)
if not task.get("id"):
    raise RuntimeError("Submission response did not contain a prediction id")
result_url = f"https://api.wavespeed.ai/api/v3/predictions/{task['id']}/result"

# 2. Poll until the prediction finishes.
while True:
    result_body = request_json(result_url)
    result = result_body.get("data", result_body)
    status = result.get("status")
    if status == "completed":
        print(result.get("outputs", []))
        break
    if status in {"failed", "cancelled", "timeout", "deleted"}:
        raise RuntimeError(result)
    time.sleep(2)
Seedream v4.5 API — Frequently asked questions
What is the Seedream v4.5 API?
Seedream v4.5 is a ByteDance model for image generation, exposed as a REST API on WaveSpeedAI. Seedream 4.5 is a next-gen text-to-image model optimized for typography—crisper text rendering, stronger prompt adherence, and up to 4K output for posters and brand visuals. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing. You can call it programmatically or try it from the playground above.
How do I call the Seedream v4.5 API?
POST your input parameters to the model's REST endpoint (shown in the API tab of this playground) with your WaveSpeedAI API key in the Authorization header. Submission returns a prediction ID. Poll the result endpoint starting around every 2 seconds, increase the interval for long-running tasks, and stop on any terminal status. The playground generates Python, JavaScript, and cURL examples for submitting requests and polling results. Full request/response shape is documented at https://wavespeed.ai/docs/docs-api/bytedance/seedream-v4.5.
How much does Seedream v4.5 cost per run or per second?
Seedream v4.5 starts at $0.04 per run or per second. That figure is the base price — the final charge scales with the parameters you set in the form (output size, length, count, references, or whatever knobs this model exposes), so a higher-quality or larger output costs more than a minimal one. The exact cost for your current input is shown live next to the Generate button before you submit, and the actual per-call charge is recorded on the prediction afterwards.
What inputs does Seedream v4.5 accept?
Key inputs: `prompt`, `size`. The full JSON schema (types, defaults, allowed values) is rendered above the Generate button and mirrored in the API reference at https://wavespeed.ai/docs/docs-api/bytedance/seedream-v4.5.
How long does Seedream v4.5 take to generate?
Reported generation time on WaveSpeedAI is around 11 seconds per request. This is an estimate, not a latency guarantee; queue time and input settings can change the total wait. live status is visible in the prediction record.
Can I use Seedream v4.5 outputs commercially?
Commercial usage rights depend on the model's license, set by its provider (ByteDance). Check the provider's applicable terms and WaveSpeedAI's Terms of Service before commercial use.
More from ByteDance
View all- bytedance/avatar-omni-humanTalking Avatar
- bytedance/avatar-omni-human-1.5Talking Avatar
- bytedance/dreamactor-v2Motion Control
- bytedance/latentsyncTalking Avatar
- bytedance/lipsync/audio-to-videoTalking Avatar
- bytedance/omni-human-2.0Talking Avatar
- bytedance/seed-audio-1.0Sound Effects Generation
- bytedance/seed-speech-tts-2.0Text to Speech
More Text to Image models
View all- bytedance/seedream-v5.5Text to Image
- bytedance/seedream-v5.0-proText to Image
- google/nano-banana-pro/text-to-imageText to Image
- google/nano-banana-2.1/text-to-imageText to Image
- openai/gpt-image-2.6-sunburst/text-to-imageText to Image
- wavespeed-ai/z-image/turboText to Image
- openai/gpt-image-2/text-to-imageText to Image
- openai/gpt-image-2.5-sunburst/text-to-imageText to Image